
|
Jingchen Sun (孙精辰)
Ph.D. Student Department of Computer Science and Engineering University at Buffalo, State University of New York Email: jsun39@buffalo.edu
|


About Me
I am a CS Ph.D. student at University at Buffalo (SUNY), advised by Prof. Changyou Chen. I received my M.S. from Zhejiang University and B.S. from North China Electric Power University.
My research broadly focuses on Transfer Learning for Multimodal Large Language Models (LLMs), particularly on employing techniques such as knowledge distillation,prompt tuning, train-free adaptation, and to enhance their application in various downstream tasks, such as visual perception, video understanding, and multimodal retrieval.
I am exploring how to use reinforcement learning methods, such as GRPO, and on-policy distillation method to enhance reasoning capabilities of multimodal LLMs. If you are interested in these topics and would like to collaborate, feel free to drop me an email!
I am on the job market and looking for a full-time industry opportunity start in 2027 !
News [Update!]
- 08/09/2026: A paper was accepted to ECCV 2026!
- 05/13/2026: I was recognized as an ICML Silver Reviewer!
- 02/21/2026: Two paper were accepted to CVPR 2026!
- 01/17/2026: One paper were accepted to ICASSP 2026!
- 11/07/2025: One paper were accepted to AAAI 2026!
- 12/20/2024: Two papers were accepted to ICASSP 2025!
- 10/28/2024: A paper was accepted to WACV 2025!
- 09/25/2024: A paper was accepted to NeurIPS 2024!
- 08/23/2024: I finished the intern at NEC Labs, great summer at Princeton !
Highlight Publications
-
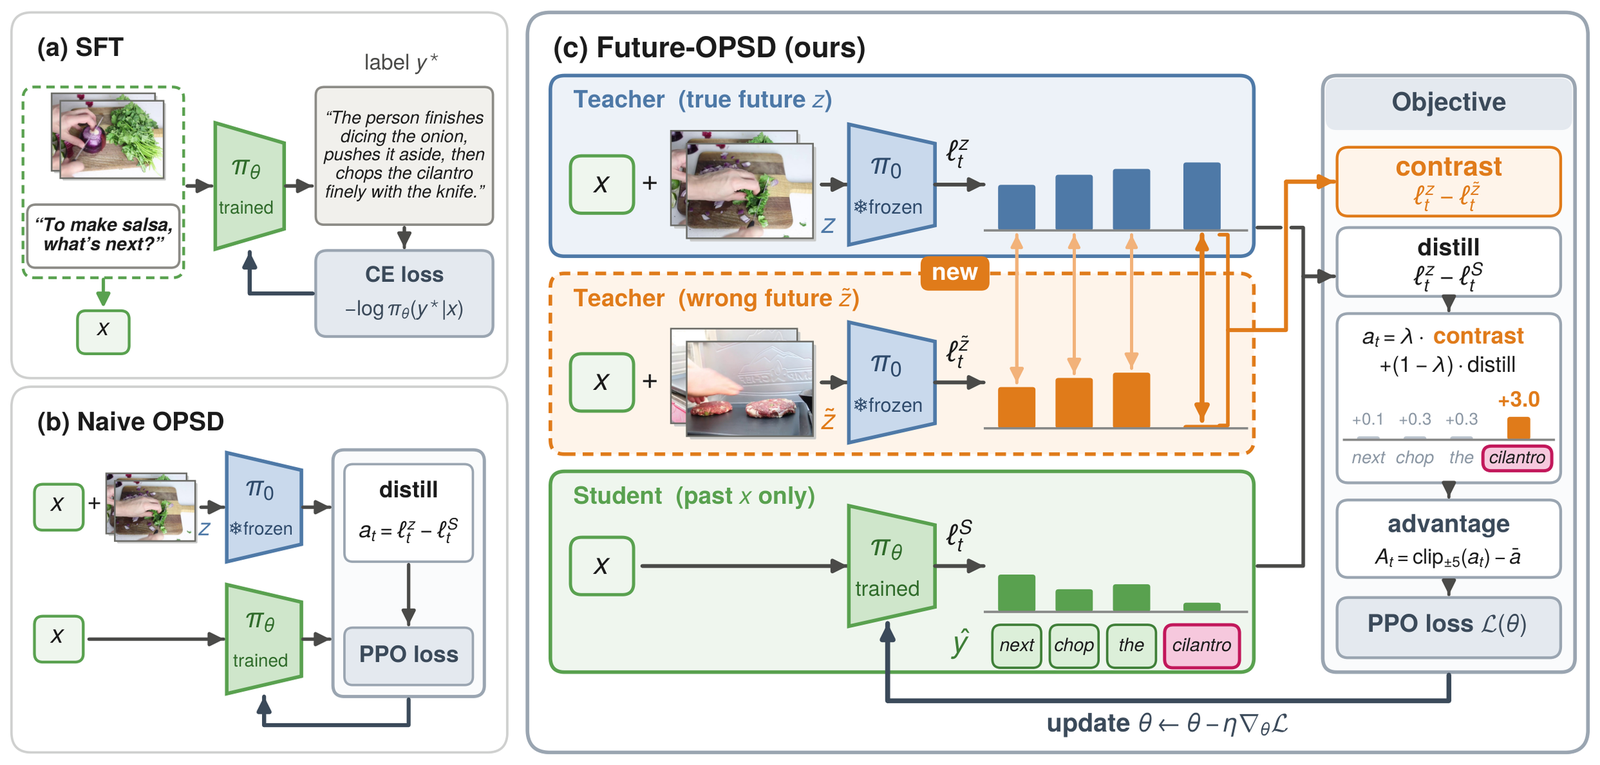
Future-OPSD: Learning Video Foresight Reasoning from Unlabeled Videos via On-Policy Self-Distillation
Jingchen Sun*, Jiaxing Zhang*, Qingqiao Hu, Dingqiang Ye, Yuqi Jia, Yijun Liang, Di Fu, Yunjie Tian, Dongdi Zhao, Changyou Chen.
We propose an on-policy self-distillation framework that learns video foresight reasoning from unlabeled past–future video pairs, focusing the model on the most valuable future information.
Preprint 2026
Webpage Code (Coming Soon) -

Beta-KD: Uncertainty-Aware Knowledge Distillation for Multimodal Large Language Models
Jingchen Sun, Shaobo Han, Deep Patel, Wataru Kohno, Can Jin, Changyou Chen.
We propose a novel uncertainty-aware knowledge distillation method, which can improve the performance of the student model by leveraging the uncertainty of the teacher model.
CVPR 2026
Code PDF Webpage -

CLAP-S: Support Set-Based Adaption for Downstream Fiber-Optic Acoustic Recognition
Jingchen Sun, Shaobo Han, Wataru Kohno, Changyou Chen.
We introduce a support set–based adaptation approach to enhance domain adaptation performance in audio-language models.
ICASSP 2025
Code PDF Webpage -

Craft: Cross-modal Aligned Features Improve Robustness of Prompt Tuning
Jingchen Sun, Rohan Sharma, Vishnu Suresh Lokhande, Changyou Chen
We propose a novel cross-modal feature alignment method that mitigates the overfitting issue in visual-language model prompt tuning across different domains.
WACV 2025
Code PDF Webpage -

PIDNet: An Efficient Network for Dynamic Pedestrian Intrusion Detection
Jingchen Sun, Jiming Chen, Tao Chen, Jiayuan Fan, Shibo He
We propose a novel dynamic pedestrian intrusion detection network, which can efficiently detect the pedestrian intrusion in the video.
ACM MM 2020
Code PDF
Internship
-
 TikTok
Research Scientist Intern
Bellevue, WA, May 2026 - August 2026 -
 NEC Labs America
Research Intern
Princeton, NJ, June 2024 - Aug 2025 -
 Nokia Bell Labs
Applied AI Researcher Intern
Murray Hill, NJ, June 2023 - Aug 2023
Conference Reviewrs
- ML Conference: NeurIPS 2024, 2025; ICLR 2025, 2026; ICML 2025, 2026; AISTATS 2025; IJCAI 2025; IJCNN 2025
- CV Conference: CVPR 2026; ICCV 2025; WACV 2025
- Audio Conference: ICASSP 2025, 2026
Journal Reviewrs
- Transactions on Machine Learning Research (TMLR): 2024, 2025, 2026
- IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI): 2026
Teaching Asistant
- CSE 474/574: Introduction to Machine Learning (2024 Spring, 2022 Fall)
- CSE 676: Deep Learning (2022 Spring)